 DIGITAL
Designing a Generative AI App Without Losing Control: Architecture, Limits and Governance
Promising automated answers is easy; keeping control over outcomes, cost and compliance in daily app operations is the hard part. This guide returns a practical roadmap to decide, design and operate AI features with criteria for PoC and production.
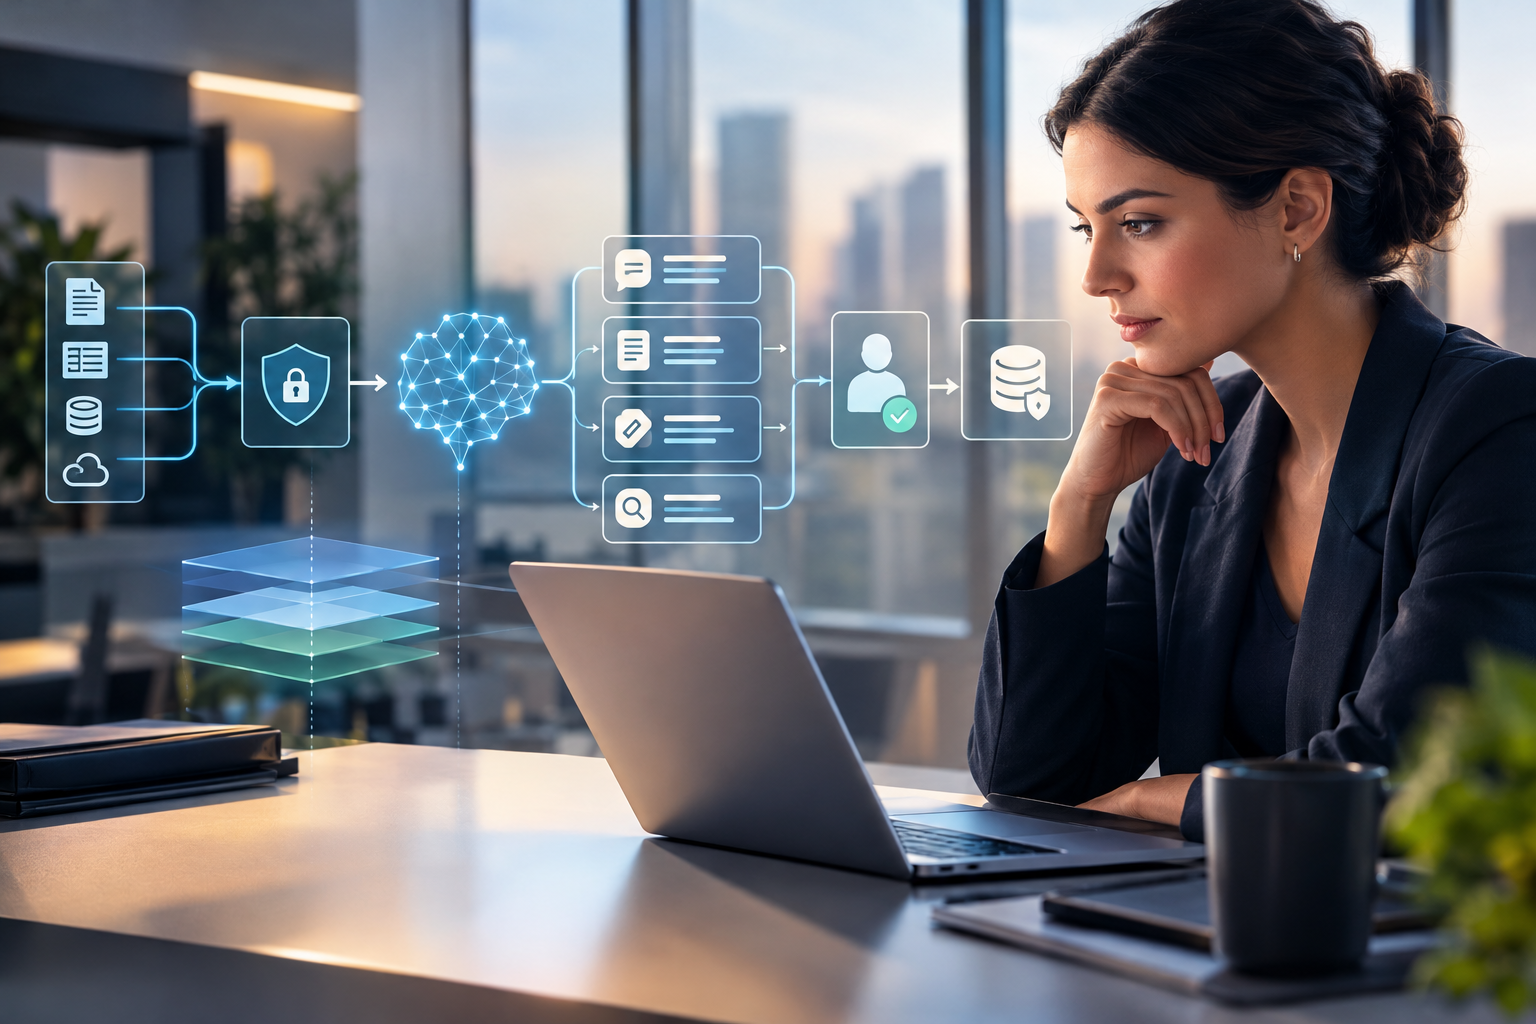
An internal assistant that accidentally changes sensitive operational records is the morning crisis no one wants. Promising automated answers is simple; ensuring the AI doesn't introduce inconsistency, unexpected cost or compliance risk is the real work. The core thesis: generative AI is a conditional utility — excellent for assistance, classification and drafting, unsafe when given autonomy over critical changes. Architecture, operational limits and prompt governance determine whether AI helps or becomes a problem.
Which AI use cases deliver operational ROI and which to avoid
Start by prioritizing scenarios with measurable impact and a controllable risk surface. Three common corporate app scenarios help decide:
Internal assistant that suggests actions (high benefit, moderate risk)
What it does: provides suggested text, response drafts or action recommendations but requires human approval before changing records. Why it works: reduces repetitive work and speeds processes. Essential limit: never allow automatic writes to sensitive data without approval.
Data enrichment and classification (high benefit, low risk)
What it does: extract entities, generate metadata and classify records to improve search and routing. Why it works: increases discoverability without touching transactional systems. Limit: validate samples and keep provenance logs for inferences.
Contextual search with embeddings (situational benefit, privacy and cost risks)
What it does: combine semantic vectors with a generative model for contextual responses. Why it works: converts large corpora into actionable answers. Limit: control what data is indexed, legal usage rights and update cadence for vectors.
When to choose on-device models vs cloud APIs
The on-device vs cloud decision is architectural with clear trade-offs. Use these practical rules:
- On-device or on-prem: choose when local latency and strict data control are essential, or when policy forbids sending data to third parties. Limitation: maintenance burden, model updates and hardware costs.
- Cloud APIs: choose when you need up-to-date models, elastic scale and fast time-to-market. Limitation: data exposure to providers and per-call costs; mitigation requires anonymization and contractual safeguards.
- Hybrid: keep embeddings local with cloud generation, or use local inference for deterministic steps and cloud for creative generation. This pattern balances control and capability.
Practical architecture: data flows and integration patterns
Recommended minimal architecture for a corporate app using generative AI:
- Ingestion and preprocessing: normalization and anonymization before any external call.
- Embeddings layer and vector DB: hosted locally or in a controlled environment to protect IP; used for contextual search.
- Prompt orchestrator: service that applies templates, token limits and usage policies before calling models.
- Inference layer: could be third-party API or on-device engine; returns drafts or suggested actions to the orchestrator.
- Human validation and blocking rules: automated checks and approval steps with logging and rollback capability.
- Observability and audit: capture metrics and traces for each inference without storing sensitive content unnecessarily.
Illustrative flow: user requests a document summary → preprocessing anonymizes PII → vector DB returns relevant passages → orchestrator builds a prompt with limits → model generates a draft → system records inference metadata and shows suggestion for human review.
Prompt governance, testing and human-in-the-loop
Governance must be operational: policies alone are not enough. Implement actionable rules product teams can apply:
- Prompt checklist: approved templates, allowed variables and negative filters. Each prompt versioned with author and timestamp.
- Controlled testing environment: A/B tests with limited traffic and scope prior to rollout.
- Human gate by category: changes that affect sensitive data require explicit approval or a suggestion-only mode.
- Data policy: define which fields may leave the environment and when to apply hashing, truncation or anonymization.
- Periodic review process: manual sampling, recalibration of prompts when recurring errors appear.
Quick prompt governance checklist
- Have approved, versioned prompt templates.
- Define context and token limits.
- Require human validation for critical changes.
- Log inputs/outputs with metadata for audits.
- Apply anonymization before external calls.
Observability and operational metrics to track
Define metrics that support clear decisions rather than fuzzy impressions. Prioritize:
- Per-call latency: monitor distributions and peaks that affect UX.
- Cost per call: understand financial impact per user journey.
- Fallback rate: share of requests where AI could not produce an acceptable result and a fallback or human path was used.
- Human override rate: how often reviewers modify AI suggestions; a practical accuracy signal.
- Unsafe generation rate: events where outputs violate policy (sensitive data exposure, inappropriate language). These should trigger automated alerts.
Instrument logs with metadata (prompt version, context source, reviewer ID) and retain only what is necessary for audits while respecting privacy rules.
PoC plan and actionable success criteria
An effective PoC has a limited scope, measurable criteria and clear operational boundaries. Structure it like this:
- Succinct objective: for example, reduce average review time in a specific flow without allowing automatic writes.
- Technical scope: data sources, whether embeddings are local, which model is orchestrated and whether APIs are used. Prefer components that can migrate from PoC to production.
- Minimum metrics: acceptable average latency, maximum fallback rate, maximum human-override rate and estimated cost per volume.
- Checkpoints: data security review, blind prompt testing, initial human audit and validation of inference logs.
- Pass criterion: agreement between AI suggestion and human reviewer above the agreed threshold on a representative sample, with no PII exposure incidents.
Operational FAQs
Can generative AI modify operational systems?
Technically yes. Best practice is to separate suggestion from execution. Enforce explicit authorization whenever flows impact sensitive or transactional data.
Can model outputs be audited?
Yes, if the system records essential inference metadata — prompt version, referenced context, model identity and reviewer ID. Avoid storing sensitive inputs verbatim unless necessary and permitted.
How to protect privacy when using third-party APIs?
Use anonymization and data minimization, and ensure contractual safeguards on retention and usage. If that is insufficient, host embeddings or inference in a controlled environment.
How to train models with proprietary data securely?
Options include internal training in controlled environments, local embeddings, or isolated fine-tuning workflows. Validate legal and exfiltration risks before engaging third parties.
Minimum governance for a PoC?
Versioned prompt templates, isolated test environment, human gate for critical changes, inference logging and a data anonymization policy. These allow iteration without exposing systems or breaking compliance.
Trade-offs and recommended first technical experiment
Trade-offs are between control and speed: cloud APIs accelerate adoption; on-device increases data control. A hybrid design — local embeddings with controlled generation via an orchestrator — often balances cost, privacy and evolution potential.
Recommended first experiment: a suggestion-only assistant integrated into a non-transactional flow, using embeddings to improve relevance. Version prompts, implement a human gate and enable observability from day one to measure operational benefit safely.
Next step to run a safe pilot
If you want to turn this roadmap into a technical PoC with controlled integration, MVX can design the flow, prompt orchestrator and observability layer aligned to your privacy requirements. To discuss a pilot and success metrics, schedule a PoC via our Automação & IA page or explore our APIs & Integrations and Custom software options.